LanguageBuddy: an AI language tutor that turns conversation into curriculum
- 3
- languages: Dutch, Italian and Spanish
- 177
- role-play scenarios
- 6,200+
- hand-curated vocabulary entries
- 336
- tests every change has to pass
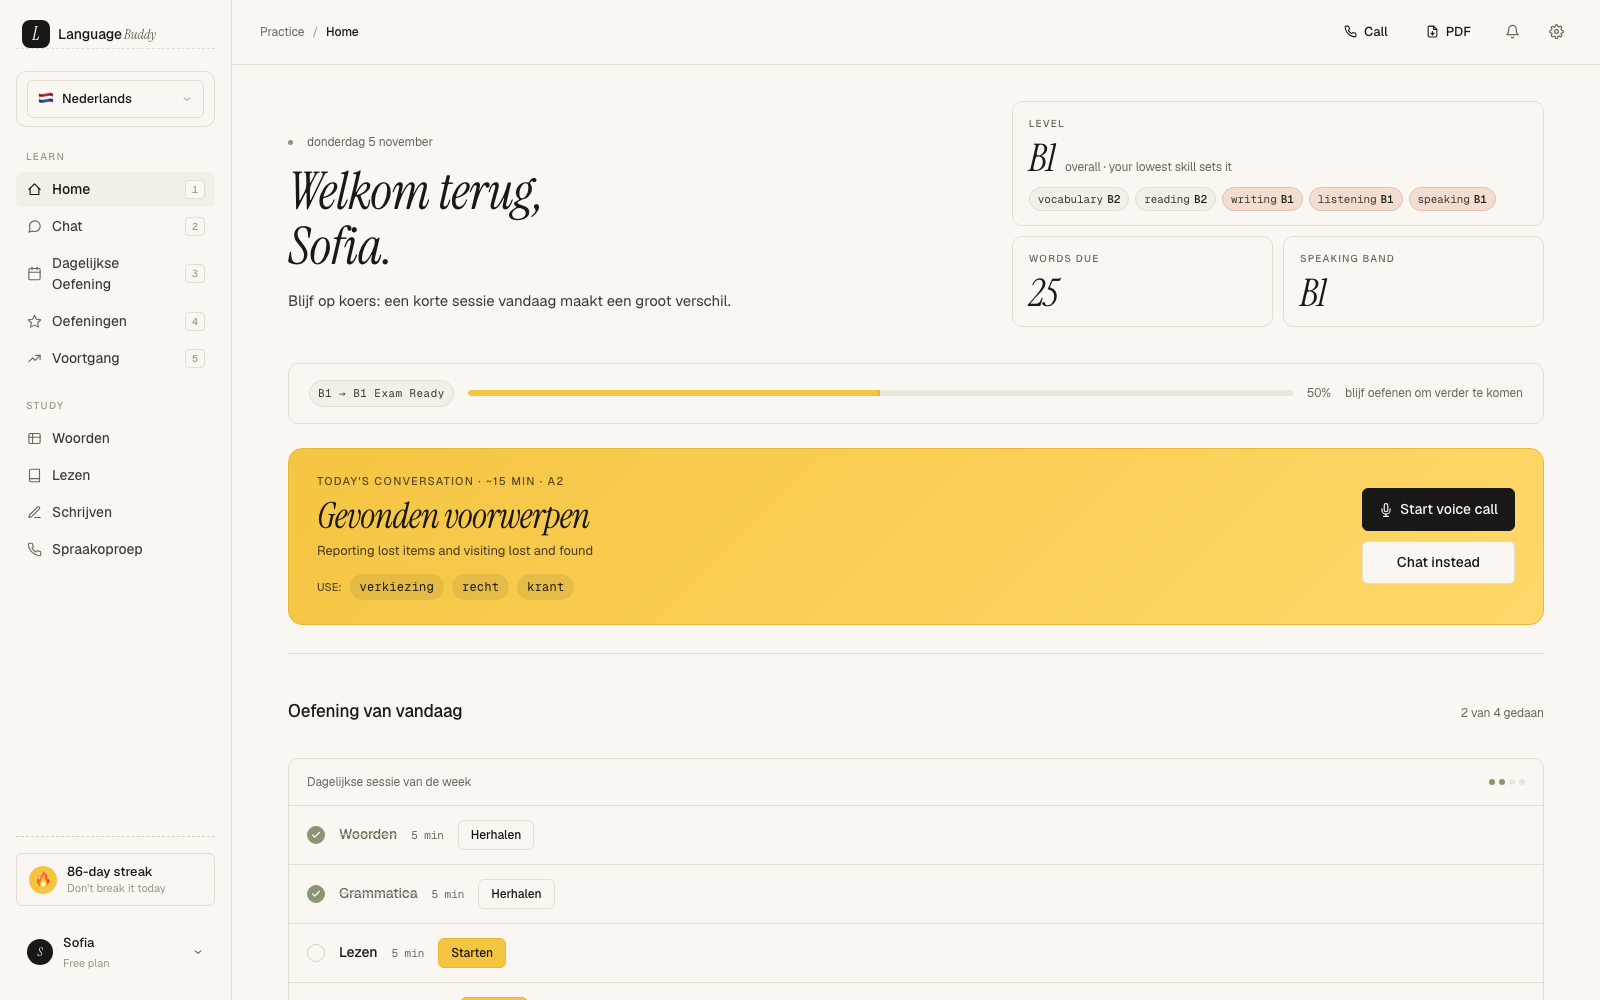
A self-hosted AI language learning platform for Dutch, Italian and Spanish (A1–C1). An adaptive CEFR placement exam scores five skills independently; daily lesson plans combine drills, listening generated with neural TTS, reading comprehension built from that day's real news, and LLM-graded writing. Free conversation (text or hands-free voice call) feeds a closed learning loop: mistakes are captured, lemmatized and scheduled by SM-2 spaced repetition into the next day's exercises and printable PDF workbooks.
The premise
The best moments in language learning happen mid-conversation: the word you reach for and don't have, the article you get wrong, the verb you conjugate by feel. Most apps let those moments evaporate. LanguageBuddy is built so they don't: a self-hosted AI tutor for Dutch, Italian and Spanish (CEFR A1 to C1) where nothing you stumble on gets thrown away. Every mistake becomes tomorrow's study material.
- You talk to the tutorconversation
- A mistake is extractedcapture
- The word is lemmatizedlemma
- SM-2 schedules itspaced repetition
- It comes back tomorrowexercise, workbook
Talk first, drill later
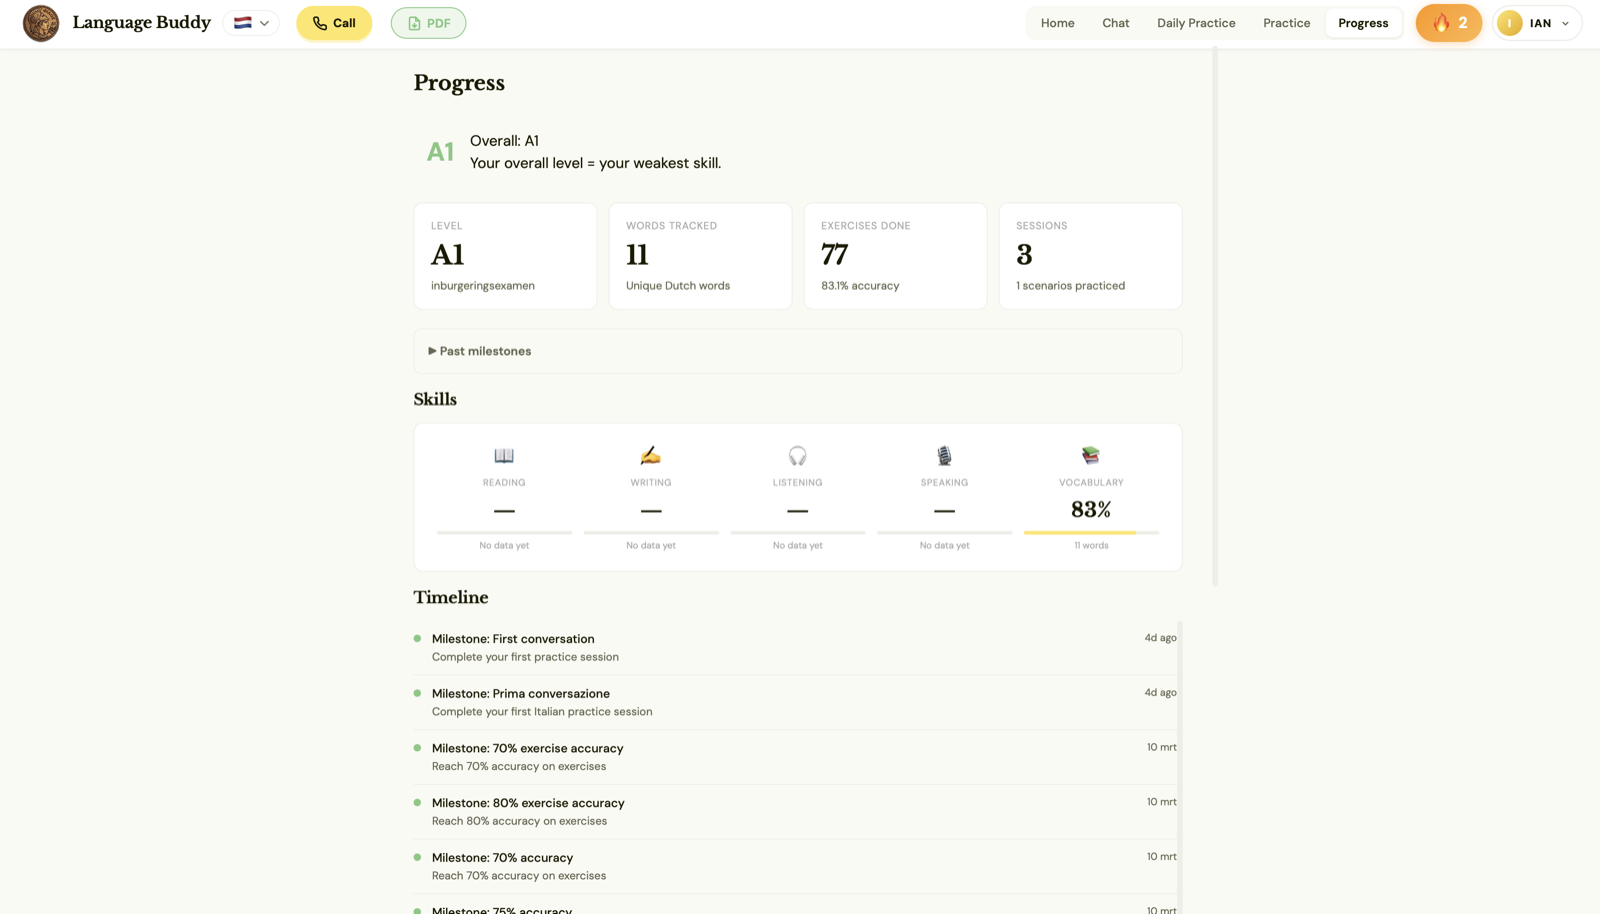
You start with an adaptive CEFR placement exam that scores vocabulary, reading, listening, writing and speaking as five separate skills, branching difficulty as it goes. Your overall level is your weakest skill, so there is no hiding behind a strong reading score.
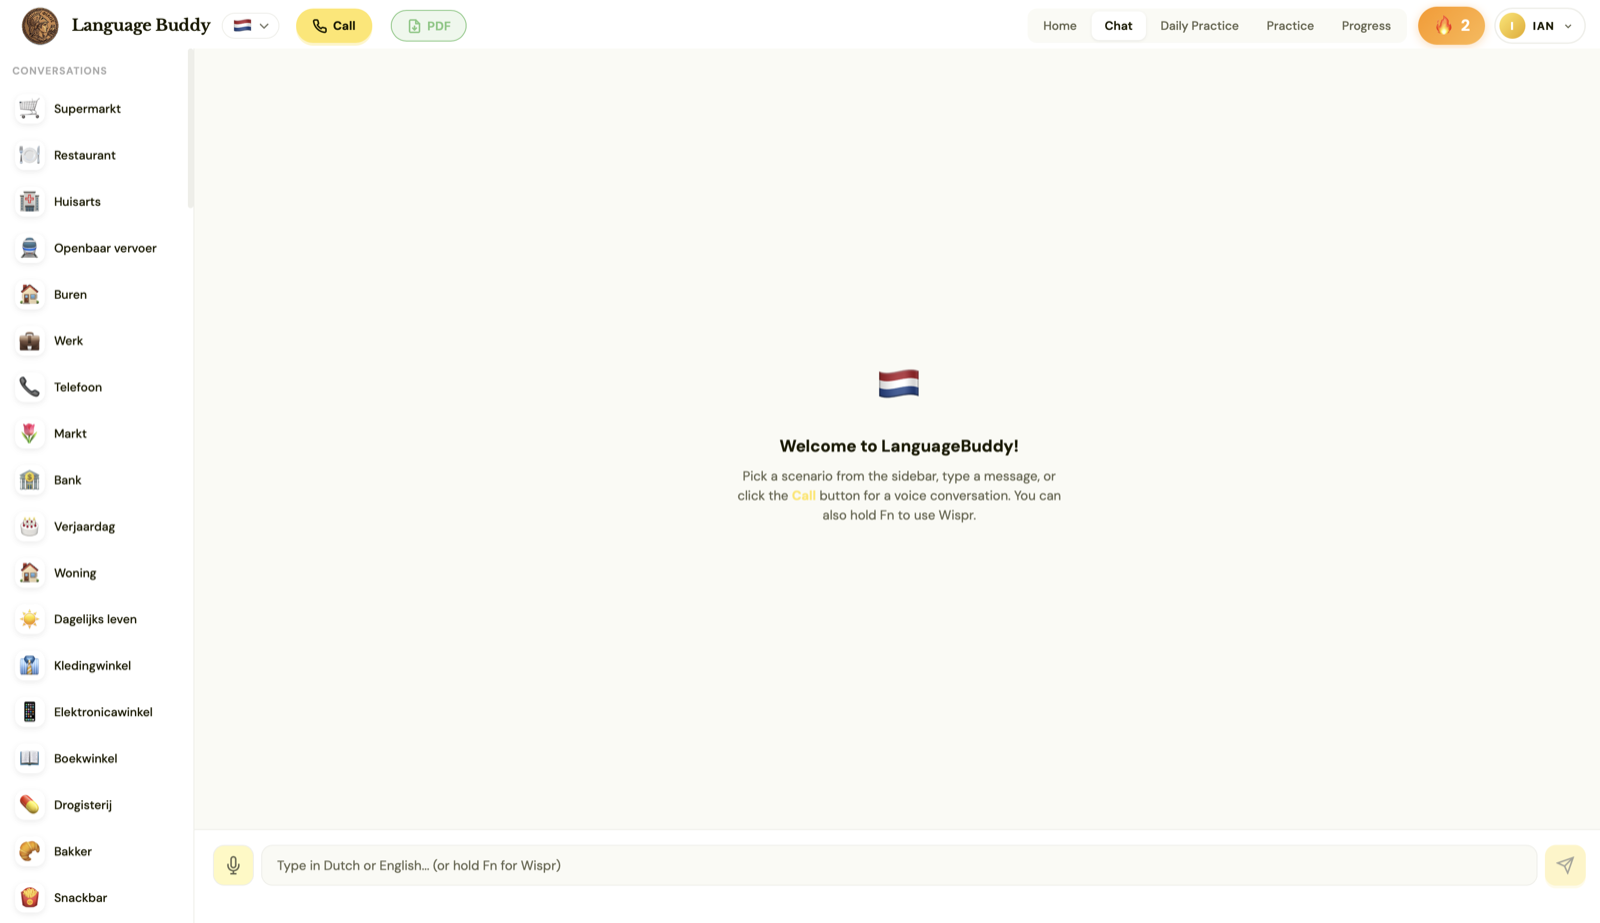
Then you talk. The core of the app is free conversation with a level-adapted LLM tutor: 177 role-play scenarios (ordering at the bakker, arguing with the huisarts, small talk with the buren) in text, or fully hands-free voice calls using in-browser speech recognition plus neural TTS.
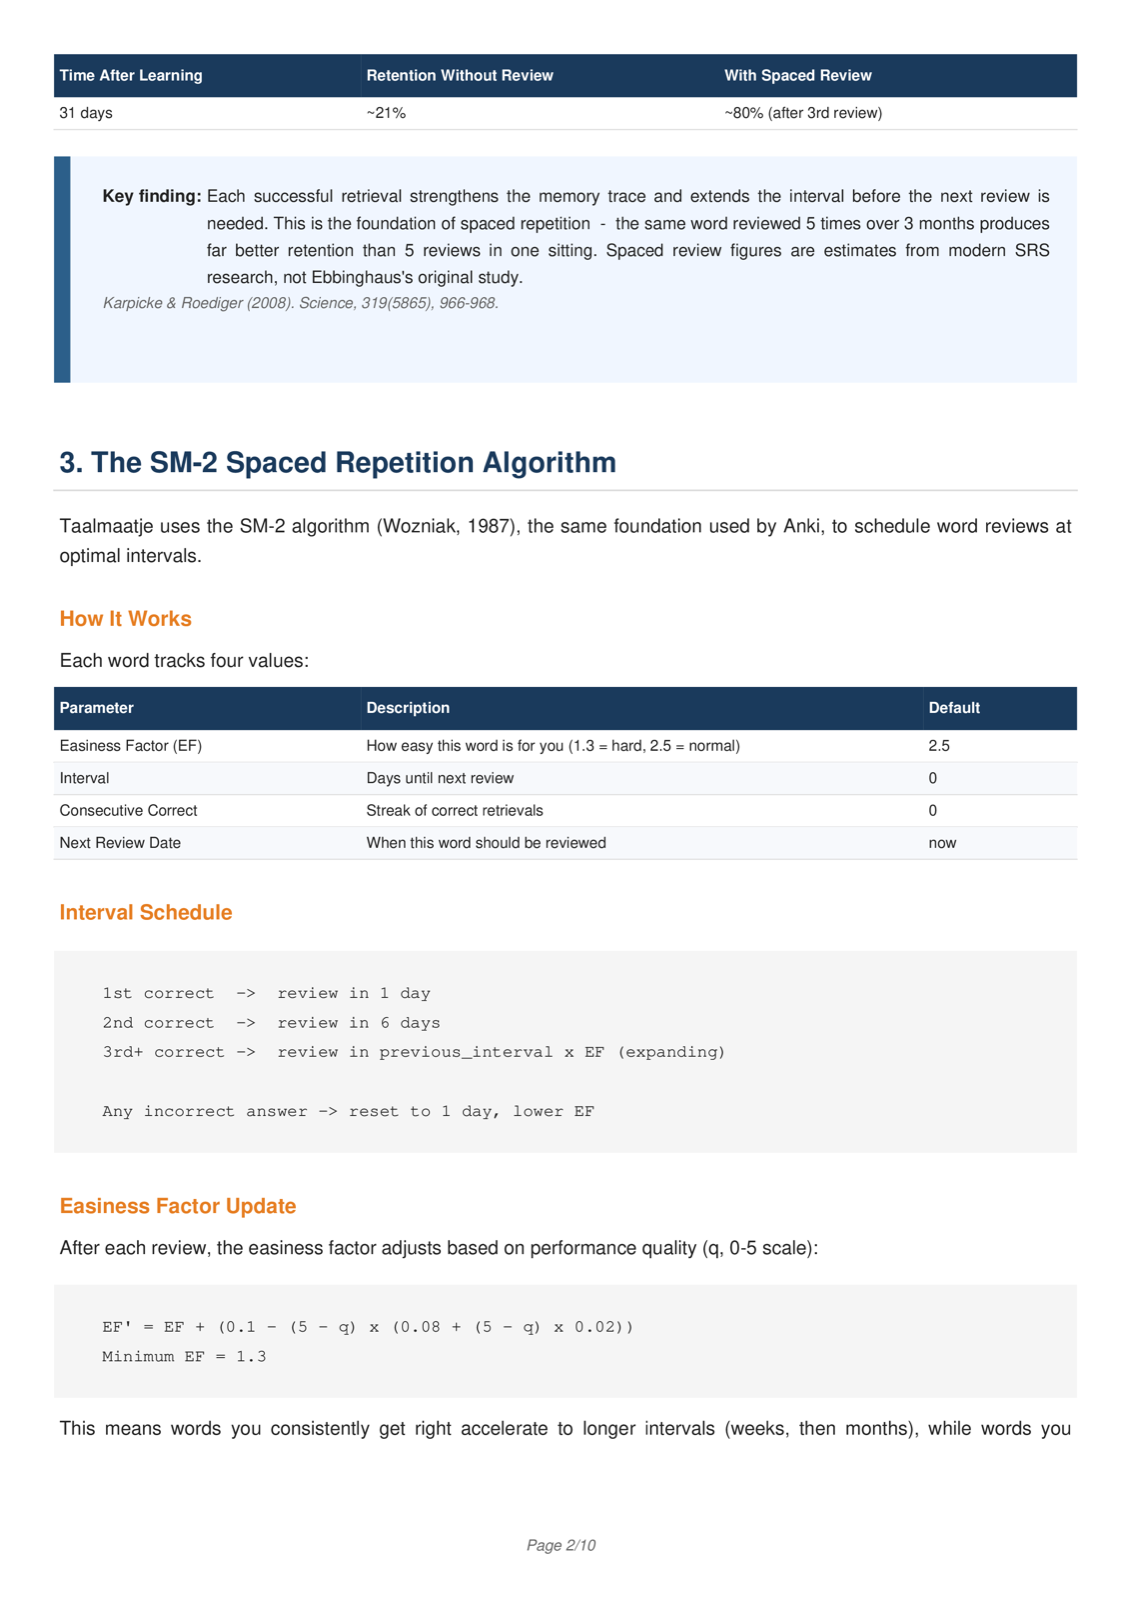
While you chat, the system listens for mistakes. Each one gets extracted, lemmatized and fed into an SM-2 spaced-repetition engine, the same algorithm family Anki uses. Those words come back in the next day's exercises and in a personalized, printable PDF workbook for offline study. Conversation in, curriculum out: that is the closed loop.
The daily grind
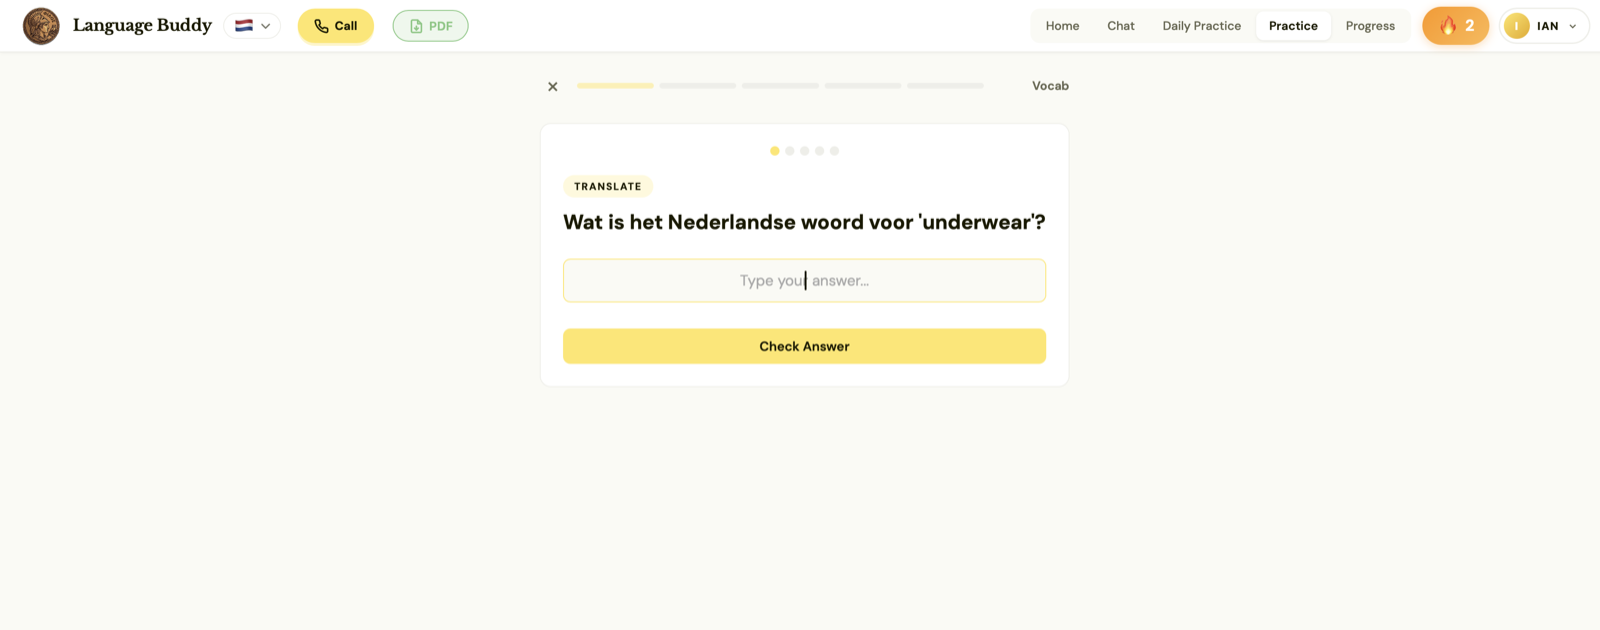
Each morning the system assembles a lesson plan: cloze, grammar, translation and matching drills; listening items generated with neural text-to-speech; reading comprehension built from that day's actual news (NOS, ANSA and EFE, scraped, cleaned and levelled); and writing prompts graded by an LLM against a CEFR rubric. Duolingo-style gamification with XP, combo multipliers, streaks, hearts and milestones keeps me coming back.
None of the scheduling is improvised. I wrote the learning methodology up as a proper document: forgetting curves, retrieval practice, and the full SM-2 interval and easiness-factor math the engine runs on.
Under the hood
The backend is FastAPI on Python 3.12 with a 35-table SQLite schema tracking sessions, transcripts, per-skill CEFR levels, vocabulary evidence and progression. LLM and TTS providers sit behind an abstraction layer, so the whole AI backend swaps via configuration. The frontend is an installable PWA with push notifications for daily nudges.
The content layer is hand-curated: 6,200+ vocabulary entries across A1 to C1 in multiple languages, the 177 scenarios, grammar topic sets and verb conjugation tables. About 2 MB of language data I actually stand behind.
The ~20,000 lines of Python were built with agentic coding: AI agents wrote most of the code, I directed. What keeps that from being vibe-coding is the harness the agents work inside: a written blueprint pins down behaviour before any code gets generated; every change has to pass a 336-test suite, with per-language end-to-end tests and dedicated CEFR-assessment tests, before it lands; and adversarial review passes give a second agent one job, breaking what the first one wrote. The agents type; the spec and the tests decide.
It ships as a small Docker Compose stack with hardened containers: read-only root filesystem, dropped Linux capabilities, tmpfs-only scratch space, health checks on every service.
Status
In active development, self-hosted, and in daily use by its first three users: me and two friends. A cost analysis keeps the conversational loop cheap. A 15-exchange tutoring session costs a few cents in API calls, which is exactly what makes running your own tutor on personal infrastructure realistic.
Written with AI, checked by me.
Back to projects