SponsoredBye: detecting sponsor segments in YouTube videos with NLP
- 15.6%
- WindowDiff, down from 99.1% for the baseline; lower is better
- 12.1%
- Pk, down from 76.0%; lower is better
- 86.2%
- macro F1, up from 56.6%
- 630 MB
- of labelled text
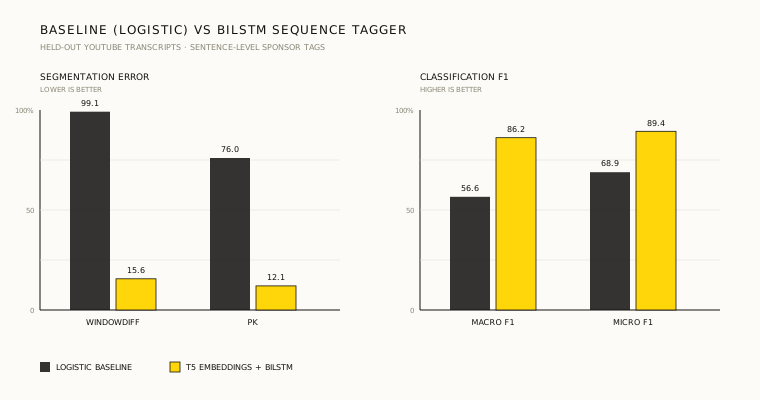
Sponsor reads are the ads you cannot skip: baked into the video, invisible to ad blockers and to YouTube Premium as it existed in 2024. SponsoredBye treats skipping them as a text-segmentation problem. Video transcripts are matched against crowd-sourced sponsor timestamps to build a labeled corpus, sentences are embedded with sentence-T5, and a bidirectional LSTM tags each sentence as sponsor or content, mapping predictions back to timestamps. Against a logistic-regression baseline the tagger cuts WindowDiff from 99.1% to 15.6% and Pk from 76.0% to 12.1%, with macro F1 rising from 56.6% to 86.2%. The write-up covers the data pipeline (transcript scraping, cleaning, punctuation restoration, MongoDB storage), the evaluation choices for fuzzy boundaries, and the planned robustness check: how much of the performance survives when giveaway words like 'sponsor' are masked out.
The ad you can't skip
By 2024, the most annoying ad on YouTube was not the pre-roll but the sponsor read: thirty to sixty seconds of "before we continue, let me tell you about today's sponsor", baked into the video itself. Ad blockers can't touch it. YouTube Premium, at the time, couldn't either; their "skip sponsor" feature shipped later. My research question, written up in the project paper, was blunt: can NLP models find the sponsored section of a YouTube video accurately enough to skip it?
SponsoredBye was a team project during my MSc at Bocconi. The premise is that a sponsor read is a text problem. It has a beginning, an end, and a register all of its own ("use code IAN for 10% off"). If you can see the transcript, you should be able to see the ad.
Building a corpus of ads
No such dataset existed in the shape we needed, so the first half of the project is a data pipeline. Crowd-sourced sponsor-segment timestamps give, per video ID, when the sponsor read starts and ends. A scraper pulls the matching transcripts and captions, the cleaning step aligns caption timings with the labeled intervals, and each sentence inside an interval gets wrapped in segment tags. The result: transcripts where every sentence carries a sponsor-or-content label, stored in MongoDB, about 630 MB of labeled text by the end.
Transcripts are hostile input. Auto-captions arrive as an unpunctuated stream, so the pipeline restores punctuation to recover sentence boundaries before anything can be embedded. Getting from "raw captions" to "clean labeled sentences" was most of the actual work, which, for anyone who has built a data pipeline before, will not come as a surprise.
- Crowd-sourced sponsor timestampslabels
- A scraper pulls the transcriptcaptions
- Punctuation is restoredsentences
- Timings are aligned with the labelsalignment
- Every sentence is sponsor or contentMongoDB
Tagging sentences, not classifying documents
The model treats the task as sequence tagging. Each sentence is embedded with sentence-T5, and a bidirectional LSTM reads the whole sequence of sentence embeddings, outputting a sponsor probability per sentence. Context is the point: "thanks to our sponsor" is obvious on its own, but the three sentences after it only read as ad copy because of what came before. Predicted sentence spans then map back to caption timestamps, which is what a skip button needs.
The baseline is a logistic regression classifying each sentence independently. It sets up the comparison that matters: how much does sequence context buy you?
- So that is how the engine works.content
- That brings us to the sponsor of today's video.sponsor
- It keeps every password in one place.sponsor
- Use code IAN for 10% off.sponsor
- Now, back to the engine.content
Scoring fuzzy boundaries
Accuracy is the wrong metric here. If the true segment starts at "That brings us to the sponsor of today's video" and the model fires one sentence late, that's a near-miss, not a random error. So the evaluation leans on segmentation metrics that score boundary placement within a sliding window: WindowDiff and Pk, both error rates where lower is better, alongside macro and micro F1 on the sentence labels.
The baseline is not a strawman; per-sentence logistic regression on good embeddings is a real approach, and it still lands at a 99.1% WindowDiff, barely better than guessing boundaries at random. The BiLSTM cuts that to 15.6%, Pk to 12.1%, and lifts macro F1 from 56.6% to 86.2%. Reading sentences in context rather than one at a time accounts for almost all of the improvement.
The caveats
The labels are crowd-sourced, so the "gold" boundaries are themselves fuzzy; that's precisely why windowed metrics were chosen over exact-match scoring. Note, however, that there is a robustness question the paper flags for future work: some words are giveaways. A model can score well by keying on "sponsor" and brand names, so the plan includes masked variants of the dataset (giveaway words and named entities removed) to measure how much understanding is left when the shortcuts are gone.
Where it went
The tagger shipped as a small live demo: paste a video, get the predicted sponsor span. The natural product form is a browser extension with a skip button, which the paper scopes out but we never built; YouTube Premium eventually shipped its own version of the feature, which felt like a fitting way for a side project to retire. The part that lasts is the method: transcripts plus crowd labels are enough to find ads in video, with the sequence model doing most of the work.
Written with AI, checked by me.
Back to projects